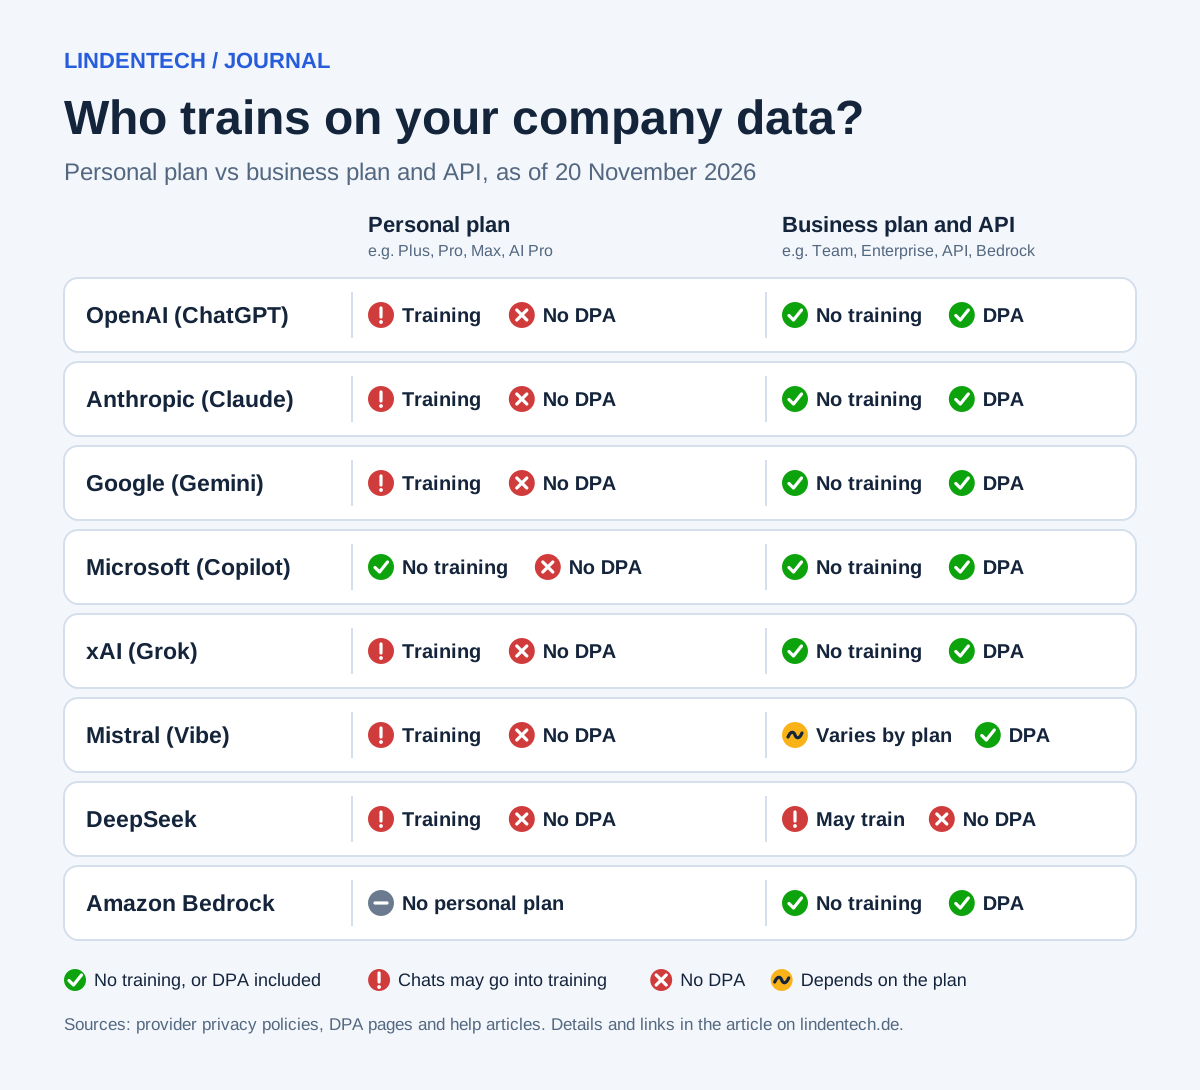
Paying for ChatGPT Plus, Claude Pro or Google AI Pro does not change how your company data is treated compared with the free version. In the personal plans of OpenAI, Anthropic, Google, xAI, Mistral and DeepSeek, your chats may be used to train the models unless you switch that off, and none of these plans comes with a data processing agreement (DPA). Through the API and on business plans, OpenAI, Anthropic and Google do not train on your data by default, and the DPA is part of the contract. Those tiers still store data for a while, usually up to 30 days for abuse monitoring.
As of 20 November 2026. This comparison is based on the providers' privacy policies, contract terms, DPA pages and help articles, plus the Amazon Bedrock documentation, all read on that day and linked below. LindenTech did not test the plans technically; we compared what the providers commit to in writing. Treat it as orientation, not legal advice.
At a glance: personal plan versus business plan and API
| Provider | Personal plan | Business plan and API |
|---|---|---|
| OpenAI | Training allowed, can be switched off, no DPA | No training, DPA included |
| Anthropic | Training allowed, can be switched off, no DPA | No training, DPA included |
| Gemini app, also with AI Pro and Ultra: training while the setting is on, no DPA | Paid API, Vertex AI, Workspace: no training, DPA included | |
| Microsoft | New Copilot app: no training according to Microsoft, no DPA | Microsoft 365 Copilot and Azure: no training, DPA included |
| xAI, now SpaceXSI (Grok) | Training allowed, can be switched off, no DPA | No training, DPA, personal data only through the zero-retention API |
| Mistral | Vibe (formerly Le Chat) Free and Pro: training on by default, no DPA | Teams: training on by default, DPA; Enterprise: no training; API: training toggle can be switched off |
| DeepSeek | Training allowed, can be switched off, data in China | No exclusion for the API, no published DPA |
| Amazon Bedrock | No personal plan | No training, model providers see no data, DPA through AWS |
The dividing line is not free versus paid but consumer versus business customer. ChatGPT Business, Claude Team and Gemini in Google Workspace are subscriptions too, yet they are treated like the API. The one exception in this comparison is Mistral, whose Teams plan also trains by default.
Five myths about AI subscriptions and company data
1. “A paid subscription protects my data”
OpenAI groups Free, Plus and Pro as services for individuals whose content may be used for training, and lists Business, Enterprise, Edu and the API as not used by default (OpenAI Help Center). Anthropic treats Claude Free, Pro and Max the same way: inputs and outputs may be used for training unless you opt out (Anthropic privacy policy). Gemini with Google AI Pro or Ultra falls under the same privacy notice as the free app (Gemini privacy notice).
2. “The API stores nothing”
The API does not train by default, but it does keep data for a short time. OpenAI retains abuse monitoring logs for up to 30 days and has not used API data for training since 1 March 2023 (OpenAI platform docs). Anthropic deletes API inputs and outputs within 30 days (Anthropic Privacy Center). Google keeps Gemini API data for 55 days to detect abuse (Gemini API usage policies). OpenAI offers zero data retention only after approval.
3. “A European provider is automatically the safe choice”
Mistral, based in Paris, stores data in the EEA by default, yet it trains on your chats by default in Vibe (formerly Le Chat) Free, Pro and even the Teams plan. Only Enterprise customers are excluded from the start (Mistral Help Center). You can switch it off under Privacy with the toggle “Allow your interactions to be used to train our models”. Where data is stored and whether it is used for training are two separate questions.
4. “Switching training off takes my old chats back”
The switch only works going forward. Anthropic states that your data remains in training runs already in progress and in models that have already been trained (Anthropic Privacy Center). OpenAI says the setting covers new conversations.
5. “A thumbs up is harmless”
Even after you opt out, OpenAI may use the entire conversation for training if you rate a response with a thumbs up or down (OpenAI Help Center). Google makes the same feedback exception and keeps Gemini chats reviewed by humans for up to three years, even if you delete them (Gemini privacy notice).
No DPA, no customer data: what the GDPR requires
If you put personal data of customers or employees into an AI tool, the provider processes it on your behalf, and Article 28 GDPR requires a data processing agreement. No personal plan offers one. OpenAI's DPA belongs to its contract terms for business customers (OpenAI DPA). Anthropic's consumer terms make clear that its commercial terms do not cover Claude.ai used as an individual (Anthropic consumer terms).
On business plans and APIs, the DPA is included automatically: at OpenAI, Anthropic, Google Cloud and Workspace, Microsoft, Mistral and AWS. xAI allows personal data only through its zero-retention API (xAI DPA). DeepSeek publishes no DPA and stores data in the People's Republic of China (DeepSeek privacy policy). Google has one detail worth knowing: for users in the EEA, Switzerland and the UK, the paid-tier data terms also apply to the free Gemini API quota (Gemini API terms).
A DPA is not the same as EU hosting, though. The second table shows where requests are actually processed:
| Route | Processing in the EU | What to watch |
|---|---|---|
| OpenAI API | Yes, with an EU project | Enabled through sales; newer models cost 10% more there |
| ChatGPT Enterprise and Edu | Yes, for new workspaces | ChatGPT Business has no EU option |
| Anthropic API and Claude Team | No | Claude in the EU only through Bedrock or Vertex AI |
| Amazon Bedrock | Yes, EU Region or EU profile | The global profile routes requests worldwide |
| Google Vertex AI | Yes, EU regions | The global endpoint gives no location guarantee |
| Microsoft Azure OpenAI | Yes, EU Data Zone | Global deployments run worldwide |
| Mistral | Yes, EEA by default | Some features use subprocessors outside the EU |
| xAI and DeepSeek | No | DeepSeek stores data in China |
Sources: OpenAI data residency, Anthropic data residency, Vertex AI data residency and Azure OpenAI data privacy. For a chatbot on your own website, see our GDPR checklist for website chatbots; the questions to ask about hosting are in Running AI in the EU.
Amazon Bedrock: Claude and other models with a DPA in the EU
Amazon Bedrock is the AI service of AWS. You call models from Anthropic, OpenAI, Amazon and other providers through your AWS account, without a separate contract with the model maker. For companies that want Claude with a DPA and processing in the EU, Bedrock is, next to Google Vertex AI, the direct route, because Anthropic itself offers no EU option.
What AWS commits to:
- AWS and the model providers do not use Bedrock inputs or outputs to train any models (Bedrock FAQ).
- The models run in accounts operated by AWS. Providers such as Anthropic have no access to your prompts and completions (Bedrock data protection).
- The AWS DPA with the EU standard contractual clauses applies automatically through the AWS Service Terms (AWS GDPR Center).
- An EU Region such as Frankfurt or an EU inference profile keeps processing in the EU. According to AWS, the global profile is about 10% cheaper but routes requests worldwide (cross-Region inference).
- You set data retention per Region. In the no-retention mode, Bedrock blocks models that require retention (Bedrock data retention).
The limit is in the abuse detection documentation: for Claude Fable 5, 5.1 and 5.2, AWS retains all traffic for up to 30 days for automated abuse checks, and AWS staff may review flagged requests. Model providers do not receive this data. Claude models released before Fable 5 are unaffected.
Checklist: switch off training in five minutes
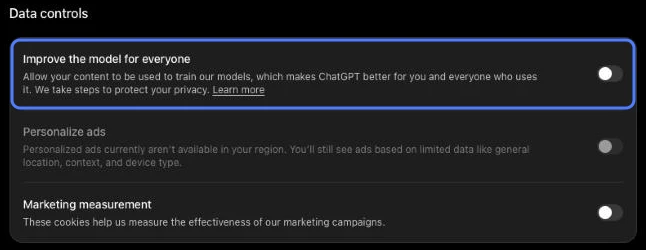
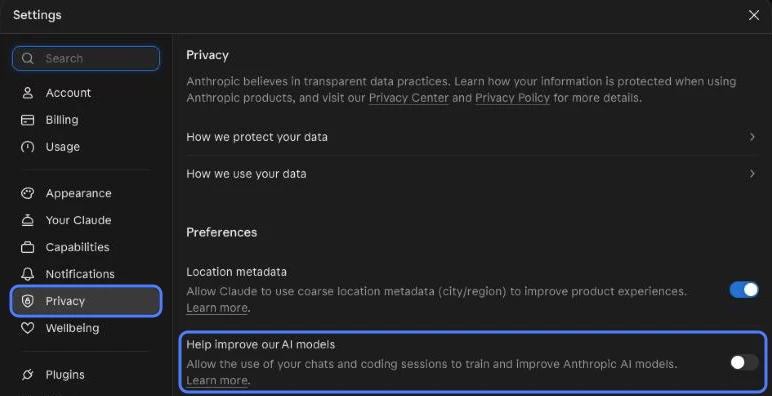
The screenshots were taken on 20 November 2026 in each service's English interface. The blue frame shows where to click.
ChatGPT
Open Settings and, under Data controls, turn off “Improve the model for everyone”. For a single confidential question, use a temporary chat; OpenAI keeps a copy for up to 30 days for safety.
Claude
Open Settings, choose Privacy on the left and turn off “Help improve our AI models”. Anthropic never uses Incognito chats for training.
Gemini
In the Gemini app, open Activity at the bottom left, or go straight to myactivity.google.com/product/gemini. Under “Help train generative AI models with”, untick “Chat content including text & attachments”. Your history stays on, and your future chats no longer go into training. Chats already reviewed by humans stay stored for up to three years.
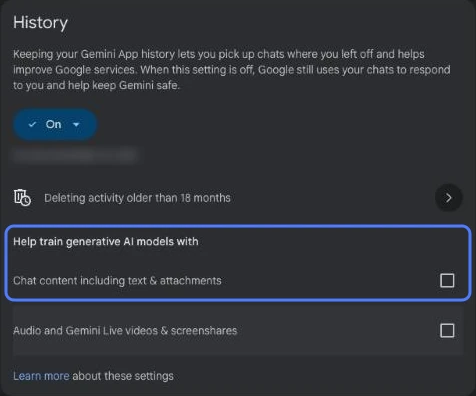
This tick box only appears in the English interface. In German and Russian, the same page shows a single switch for saving your activity (“Aktivitäten speichern”, «Сохранять историю действий»); turning it off also stops training, but new chats no longer appear in your history. Adding ?hl=en to the address shows the English version.
Vibe by Mistral and every other service
In Vibe, disable “Allow your interactions to be used to train our models” under Privacy. On the Teams plan, the admin can switch it off for everyone. And for every service: no thumbs up or down on chats that contain company content.
These switches only control training. For customer and employee data, a personal plan still lacks the DPA.
Which data belongs in which plan
| Data | Fits | Does not fit |
|---|---|---|
| Public texts, research without personal data | Any subscription with training switched off | Confidential content in the same chat |
| Internal documents, quotes, calculations | Business plan or API | Personal plan |
| Customer and employee data | Business plan or API with a DPA, ideally with EU processing | Personal plan, DeepSeek |
| Health data and other Article 9 GDPR data | Only after review with your data protection officer, API with EU processing and no retention | Any subscription |
Template: AI usage policy for your team
You can copy and adapt this page. It does not replace a review by your data protection officer.
Title of your policy: “AI usage policy of [Company], as of [date]”.
- Approved tools: For company data we only use [e.g. ChatGPT Business, Claude Team, our AI platform]. Personal AI accounts such as ChatGPT Free, Plus and Pro, Claude Pro or Gemini with a personal Google account are not allowed for company data.
- Never put into an AI tool: passwords, credentials and API keys, health data and other Article 9 GDPR data, and customer data in tools without a DPA.
- Allowed: customer and employee data only in the tools from point 1, as little as necessary and without names where possible.
- Settings: training is switched off in every account we use. We do not rate chats that contain company content.
- Check the output: a person reads AI answers before they go to customers.
- Contact: questions and incidents to [name, email].
How we handle this in the LindenTech AI Platform
Our LindenTech AI Platform uses no subscriptions, only APIs. Every request goes through OpenRouter's EU endpoint with the requirement that only providers with zero data retention and no data collection may serve it. Behind it are the EU endpoints of Amazon Bedrock, Microsoft Azure, Google Vertex AI or Mistral. The model list contains only models with such endpoints and is checked automatically every week.
The DPA and all subprocessors are public on the platform's DPA page. It also states the limit: OpenRouter is a US company, so access from the US cannot be ruled out completely. From 1 January 2027 at the earliest we are moving to Google Vertex AI in the EU; Google may then store requests flagged by its abuse detection for up to 90 days in the EU, which the DPA page also says.
Frequently asked questions
Does ChatGPT Plus train on my data?
It may, unless you turn off “Improve the model for everyone”. Plus has the same data terms as the free plan, and a thumbs up or down can still send the whole conversation into training.
Is ChatGPT Business (formerly Team) GDPR compliant?
ChatGPT Business does not train on your data by default, and the DPA is part of the contract terms. EU data storage, however, is offered only for Enterprise, Edu and the API. Check with your data protection officer whether that is enough for your data.
Can I use Claude in a GDPR compliant way?
Claude Team, Enterprise and the Anthropic API do not train by default and include a DPA. Anthropic itself does not offer EU processing; for that, use Claude through Amazon Bedrock or Google Vertex AI in an EU Region.
Does ChatGPT Enterprise train on my data?
Not by default. OpenAI uses inputs and outputs from Business, Enterprise, Edu and the API only if you explicitly agree.
Do I need a separate DPA for the OpenAI API?
No, OpenAI's DPA is part of its contract terms for business customers and applies automatically. Still check the subprocessor list and whether you need an EU project.
If you want to know which AI tools in your team see which data, and what moving to an API with a DPA would involve, talk to us about AI automation and assistants. Bring a list of the tools your team uses today and the data that ends up in them.